

- Go to AI Universe → AI Chatbot/Search → Training Center.
- At the top you see the numbers: Total, Pending, Processing, Completed, Failed and Tokens (how much AI was used).
- Below is the list of items. Use the filters to show only one source or one status.
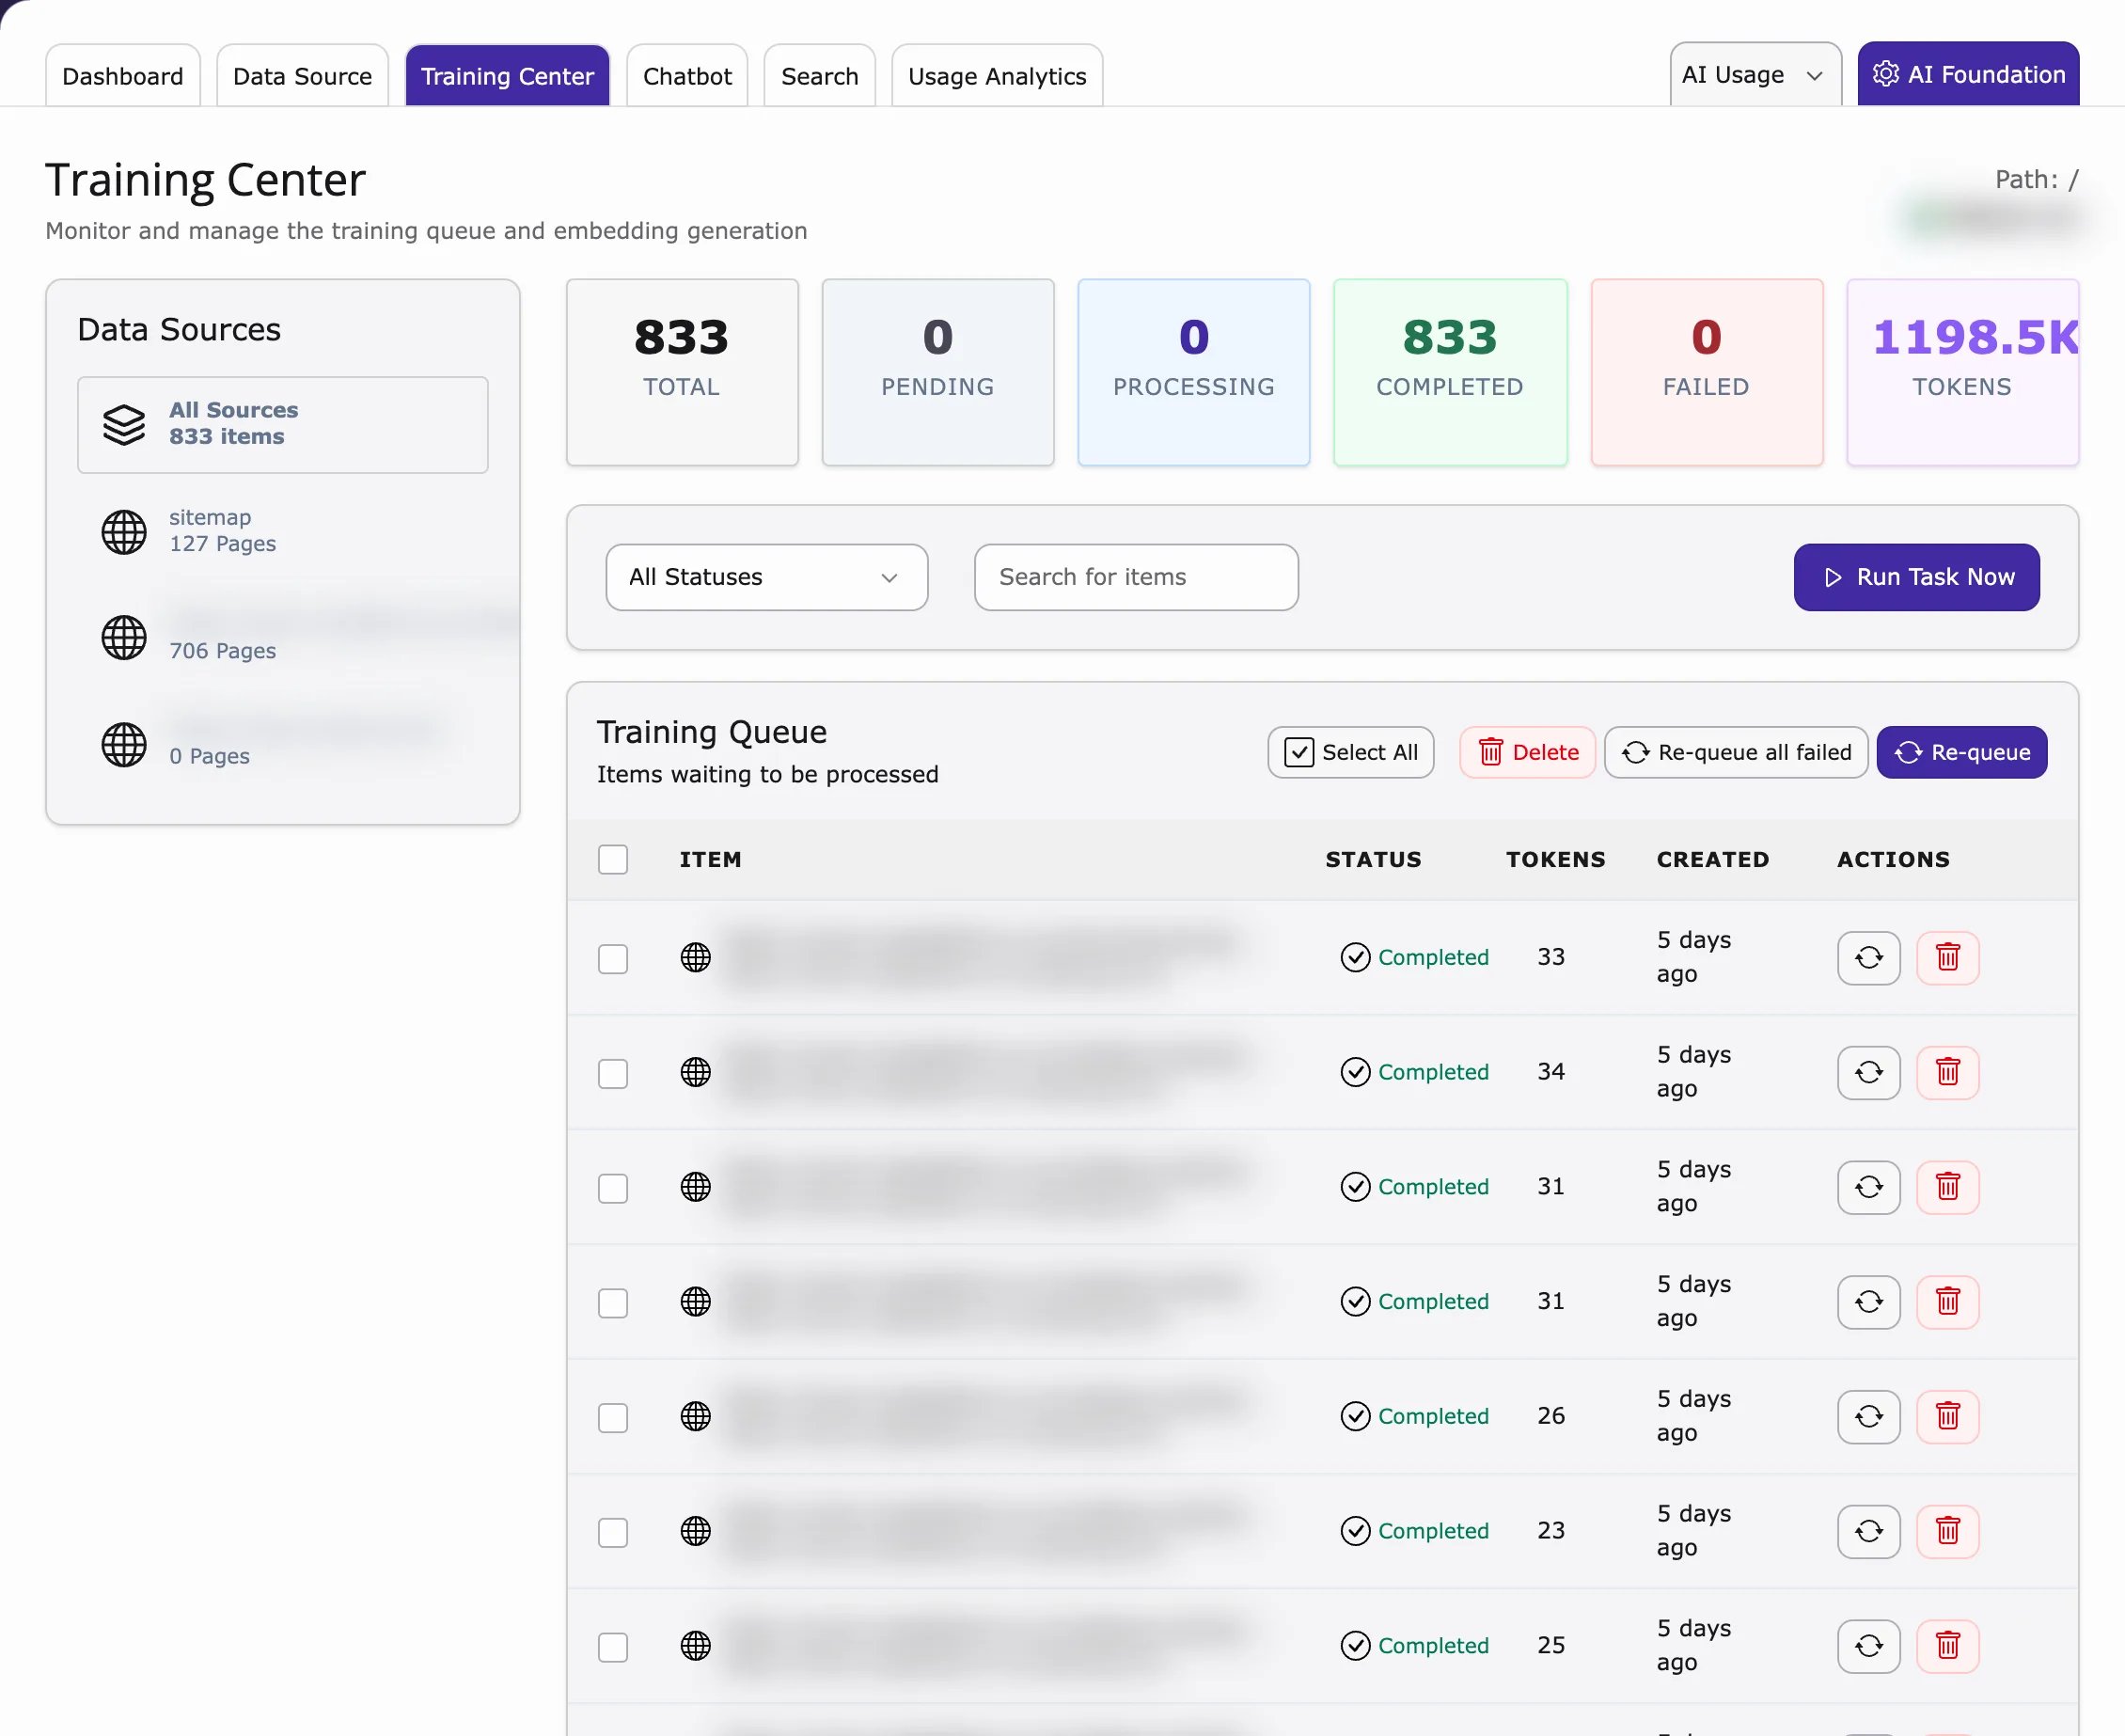
- Pending – waiting to be learned.
- Processing – being learned right now.
- Completed – learned. AI Search can use it.
- Failed – something went wrong.
- Select the item (for example a Failed one).
- Click Re-queue. The item goes back to Pending.
- Click Run Task Now to start training.
- Select the item.
- Click Delete. AI Search will no longer use this content.
Scheduler
Training runs in the background with the TYPO3 Scheduler (the TYPO3 tool that runs tasks automatically at set times).- Each website has one task called T3CS Training (Site N). N is the page ID of your website’s start page.
- AI Search creates this task for you when you save your first data source.
- To start training right away, click Run All on the Dashboard or Run Task Now in the Training Center.
- Reads the sources again that you marked with Sync.
- Trains all new content (status Pending).
- Deletes old Failed items after the number of days in Retention Days. Trained content is kept.
Sync only marks content to be read again. The AI learns it when the training task runs.
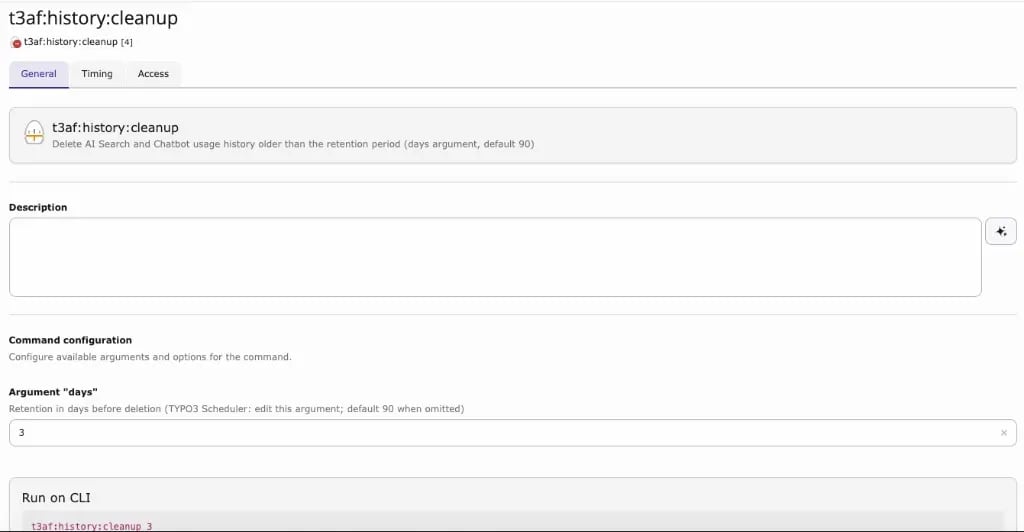
- Go to the Scheduler module.
- Create a new task and choose Execute console commands.
- Choose
t3af:history:cleanup. - Enter the number of days to keep (default: 90).
- Set how often it runs on the Timing tab.
- Save.
Training settings
How content is split, embedded and searched is set on the shared Training card (AI Features > Training card in the AI Foundation backend module, badge AI Chatbot/Search). It applies to both AI Chatbot and AI Search, including the new Retriever (hybrid or legacy), Repeated blocks, Query analysis and Keyword search options. Run a sync after changing Retriever or Repeated blocks. The same settings are also described for AI Chatbot.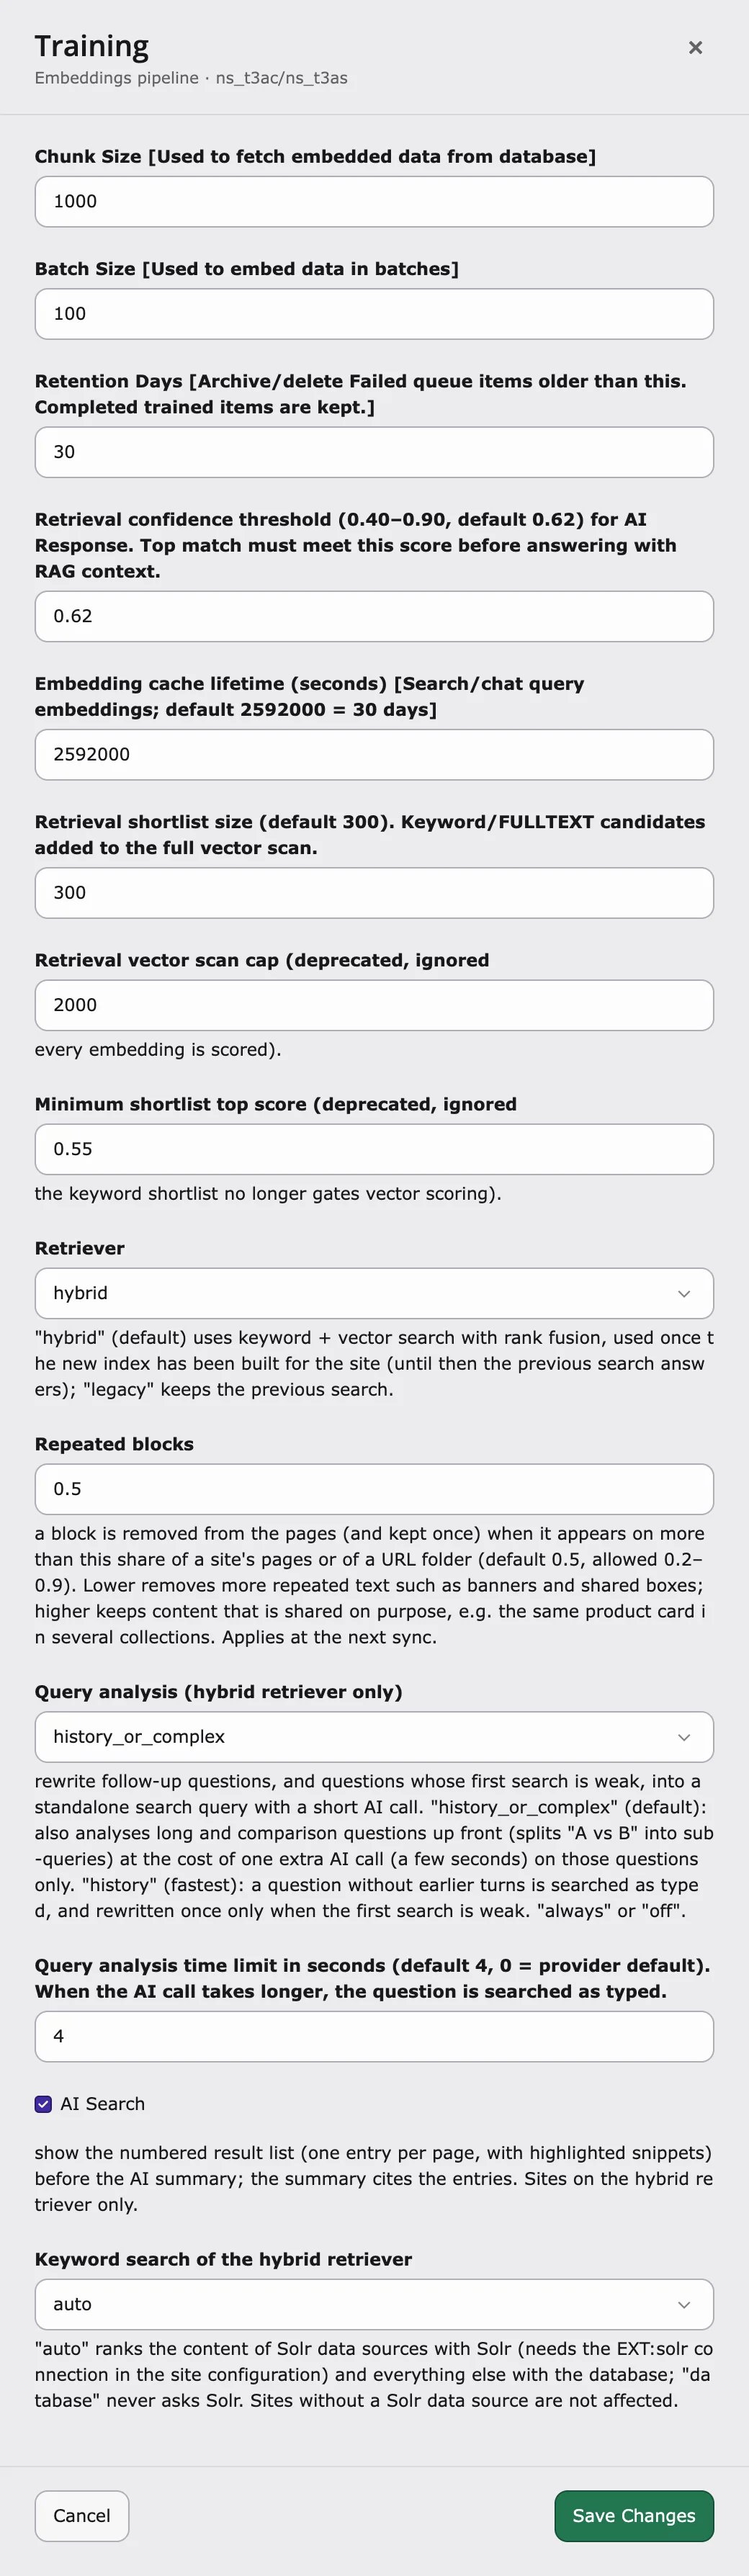
Retrieval options explained
These options change how the AI finds content for an answer. They apply to AI Chatbot and AI Search (same settings: AI Chatbot: Retrieval options). Most websites can keep the defaults. Retriever – default:hybrid
Decides which search finds the content for an answer.
hybrid– runs a keyword search and an AI (vector) search at the same time and merges both rankings. Exact words (product names, article numbers) and similar meanings are both found. A site only uses it after its data sources were synced and trained with the new index; until then it keeps answering with the previous search, so nothing breaks while you switch.legacy– keeps the previous search only.
hybrid. Choose legacy only as a temporary fallback, for example if answers got worse after an update, while you report the problem.
Repeated blocks – default: 0.5 (allowed 0.2–0.9)
Removes text that repeats on many pages, such as promo banners, “shop the video” boxes, call-to-action boxes or legal notes. Such a block is kept once instead of on every page, so it does not push real content out of answers. A block counts as repeated when it appears on more than this share of the pages – across the whole site or within one URL folder (for example all /products/ pages) – and on at least 5 pages. Headings are never removed. Sites or folders with fewer than 10 pages are left alone. Empty or invalid values use 0.5.
- Lower (for example
0.3) – removes more repeated text. - Higher (for example
0.7) – keeps content that is shared on purpose, for example the same product card in several collections.
history_or_complex (only with the hybrid retriever)
Decides when a short extra AI call turns the visitor’s question into a better search query. Follow-up questions such as “and how much is it?” are rewritten into a standalone question; comparison questions (“A vs B”) are split into one search per item.
history_or_complex– analyses follow-up questions, and also long or complex questions up front (more than 12 words, or with comparison, negation or “and/or” words). Costs one extra AI call (a few seconds) on those questions only.history– fastest. A question without earlier messages is searched as typed. Follow-ups that depend on the conversation are analysed, and a question is rewritten once when the first search finds little.always– every question is analysed. Most accurate, but slower and uses more AI credits.off– never analysed; every question is searched as typed. Follow-up questions may then find the wrong content.
history if answers must be faster, always if visitors ask many comparison questions.
Query analysis time limit – default: 4 seconds
How long the extra AI call of Query analysis may take. If it takes longer, the question is searched as typed, so a slow AI service cannot block the answer. 0 uses the time limit of the AI provider. When to change: raise it if your AI provider is often slow and follow-up answers miss; lower it if answers must start faster.
AI Search (result list) – default: on (only with the hybrid retriever)
AI Search shows a numbered result list – one entry per page, with highlighted snippets – before the AI summary. The summary refers to these entries. Switch it off to show only the AI summary. It does not affect the chatbot.
Keyword search of the hybrid retriever – default: auto
Decides which engine runs the keyword part of the hybrid search.
auto– content of Solr data sources is ranked by Solr; everything else by the database. Needs the EXT:solr connection in the site configuration. Sites without a Solr data source are not affected.database– the database is always used; Solr is never asked.
database if Solr is slow, not reachable or not set up on this server.
Deprecated options (ignored)
- Retrieval vector scan cap – no longer used. Every stored item is now compared, so no item can be missed because of a limit.
- Minimum shortlist top score – no longer used. The keyword shortlist no longer decides whether the AI (vector) search runs.
All training settings and their defaults
All training settings and their defaults
Command line
The same commands are described for AI Chatbot.For developers: run training on the command line
For developers: run training on the command line
You can start the training yourself on the command line instead of waiting for the Scheduler, for example to test it or to train everything again. The commands come from the shared AI Chatbot/Search core and work the same for AI Chatbot and AI Search.Run them with Run the Scheduler task – Compound words – See all options with
vendor/bin/typo3 (Composer), php typo3/sysext/core/bin/typo3 (non-Composer) or ddev typo3 (DDEV).Training – nst3af:training [rootPageId]Syncs the data sources of a site, trains all Pending items (creates the embeddings) and cleans up old Failed items. rootPageId is the ID of the site root page. The aliases t3cs:training and aiuniverse:training run the same command.scheduler:run --task=<taskUid> -fRuns the site’s T3CS Training (Site N) task directly, with the options saved on the task. The task UID is shown in the Scheduler module.t3cs:keyword:compoundsAdds the parts of compound words (for example “Sonnen” and “schutz” from “Sonnenschutz”) to the keyword index of already trained content, so the keyword search of the hybrid retriever also finds the single words. No AI calls, no new embeddings. Run it after a training on sites with compound words, for example German.vendor/bin/typo3 nst3af:training --help.For developers: run history cleanup on the command line
For developers: run history cleanup on the command line
t3af:history:cleanup [days] deletes AI Search and AI Chatbot usage history (visitor searches, conversations) and request traces older than days (default 90). It is separate from the training cleanup. The alias t3cs:history:cleanup runs the same command. You can also add it as a Scheduler task (Execute console commands).